Quick introduction
Teams that deploy an AI welcome avatar backed by a RAG knowledge base face a concrete risk: factual errors or hallucinations can appear in responses visible to visitors. These errors undermine trust, service quality and information security. This article provides an operational framework to measure factuality, detect hallucinations in testing and production, and implement remediations that respect the 24/7 availability requirements of a reception service.
Why measure factuality for a welcome avatar
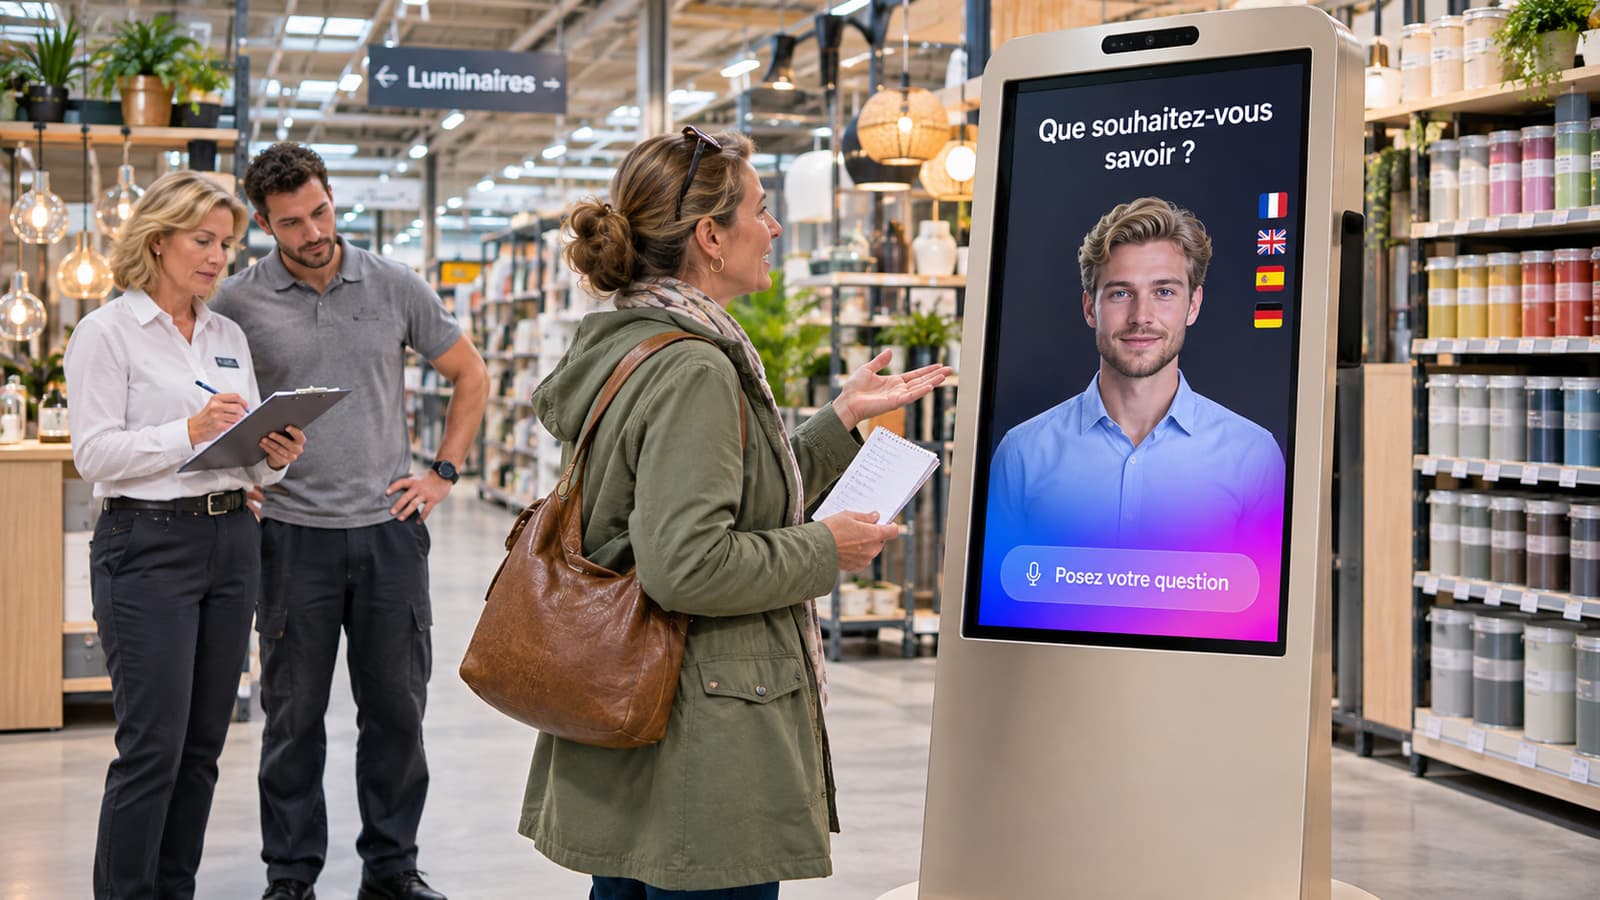
A welcome AI avatar serves as the first point of information in a physical environment. Unlike an internal tool, its answers are public and directly affect the organisation’s image. Measuring the frequency and severity of factual errors helps prioritise corrective actions, define acceptable SLAs and select mitigation patterns appropriate to the risk level (commercial information, regulatory advice, safety directions, etc.).
Measuring is not limited to counting errors. You must characterise risky situations, distinguish minor from critical errors and provide technical and business teams with actionable indicators to steer improvements.
Define usable factuality metrics
Before any instrumentation, agree with business teams on a set of simple, actionable indicators. Here are metric types to consider, presented as options to adapt to your context:
1. Incident rate on an annotated sample. This is a manual sampling measure to estimate hallucination frequency for representative interactions.
2. Rate of responses with provenance (source citation) when the RAG setup allows it. The presence of a documented excerpt reduces perceived risk but does not eliminate error.
3. Divergence score between the generated answer and the retrieved documents. Depending on the architecture, semantic search may provide a similarity score usable as an alert signal. This signal must be interpreted alongside other signals and logs, and requires appropriate configuration.
Build test sets and offline protocols
Offline tests let you spot trends before they impact users. Create several test sets:
1) Business regression set: typical questions extracted from FAQs, PDF/DOCX/XLSX/TXT/CSV documents and critical use cases validated by knowledge managers. Annotation: each expected answer is documented and signed off by a business referent.
2) Adversarial set: questions crafted to provoke hallucinations (ambiguities, composite questions, entity manipulation). These cases test the robustness of generation and RAG contextualisation.
3) Out‑of‑scope set: utterances outside the knowledge perimeter that should lead to an "I don't know" response or a handover to a human. Verify the system does not wrongly "complete" answers.
Automatic detection in production: signals and practices
In production, automatic detection relies on a combination of signals from the RAG chain, the LLM and the interface. Useful signals include:
• metadata from semantic search (similarity score, list of returned source documents);
• generation‑related indicators (if the engine exposes scores or configurable heuristics);
• interface events: repeated clarification requests, immediate user rephrasing, explicit user signals (feedback button, thumbs‑down);
Collecting and correlating these signals in an observability platform allows triggering investigation workflows.
Start with simple rules (for example correlation of a low similarity score and negative feedback) then refine with anomaly detection models.
Operational mitigation patterns
When detection flags a risky response, several mitigation patterns can be applied depending on severity and configuration:
1. Conservative fallback: prefer a constraint response (for example indicate the question requires verification) rather than a potentially incorrect answer. This is an editorial and UX choice.
2. Source‑first: configure the avatar to cite the source or indicate the provenance of the information when the response relies on the RAG base. Citation reduces surprise and helps users and business teams check.
3. Call‑to‑verify via tools and webhooks: when integration is possible, trigger a function call or webhook to an external verification service or a business API. This capability requires a specific integration and must be documented in the project architecture.
Multi‑LLM orchestration and cascade verification
An effective strategy to reduce factual errors is the orchestrated use of multiple models. Examples of applicable patterns depending on setup:
• Risk‑based routing: send simple requests to an efficient, low‑cost model and requests flagged as high risk to a more robust or specialised model.
• Verification cascade: initial generation by one LLM, then re‑evaluation or reformulation by a second engine that checks coherence with RAG passages. This implementation is advanced and requires an orchestrator and shared decision criteria.
These patterns can be combined with function calls to perform external factual checks. Any multi‑LLM orchestration must be tested offline and instrumented to monitor latency and cost.
Human‑in‑the‑loop workflow and correction cycles
Sustainable correction of hallucinations requires a structured human process. A recommended operational workflow includes:
• Automated triage: flagged interactions are placed into a review queue for human assessment. This queue must include the conversational context and the source documents used by the RAG.
• Annotation and remediation: knowledge managers validate the correct answer and, if needed, correct or enrich the knowledge base documents. Changes must follow existing KB governance (validation, versioning, tests).
• Regression tests: integrate corrected cases into the regression set to prevent regressions when updating the model or the document base. Review cadence and involved roles should be defined according to criticality.
SLA, alerting and monitoring organisation
To make these mechanisms actionable for IT teams and knowledge teams, formalise a few operational elements:
• define qualitative alert thresholds and escalation procedures agreed between IT, knowledge managers and product teams;
• integrate factuality signals into the SRE monitoring platform to obtain distinct business and technical alerts;
• provide a runbook explaining verification, correction and rollback steps when a drift is detected. The runbook should specify who edits the knowledge base and how to validate the effectiveness of measures taken.
Frequent mistakes and points of vigilance
Some common mistakes observed in RAG/LLM projects and advice to avoid them:
• Expecting a universal "confidence" from the LLM. Do not treat a model‑generated score as absolute proof. Prefer correlating several signals and having a human validate critical cases.
• Not versioning test sets. Without history, you cannot measure regressions after a model or document update.
• Confusing 24/7 availability with tolerance for errors. Maintaining availability must not obscure the need for a conservative fallback when uncertainty is high.
Quick operational checklist
Before launching a pilot or going live, check that you have:
Annotated and versioned business and adversarial test sets.
Instrumentation of RAG and LLM signals exported to the observability platform.
Defined human‑in‑the‑loop triage workflow and assigned roles.
Fallback policy and UX rules for risky responses.
Alert plan and SRE runbook including business contacts.
Conclusion and practical next steps
Measuring and reducing hallucinations of a RAG‑fed AI welcome avatar requires an approach combining clear metrics, rigorous tests, production detection and human‑driven correction workflows. Several technical patterns contribute to mitigation: conservative fallbacks, source citation, function calls for external verification and multi‑LLM orchestration according to criticality. These elements must be integrated into knowledge base governance and the organisation’s SRE practices.
SANIA can be configured to use a private knowledge base, leverage RAG semantic search, orchestrate multiple LLMs and trigger function calls or webhooks according to the chosen architecture. To assess how these patterns could apply to your reception context, you can request a SANIA demonstration and discuss an adapted pilot protocol.